AI Chat Web Search Explained: Reading Citations Right
AI chat web search explained: what gets fetched, what gets quoted, and how to check a citation before you trust Claude, GPT, or Grok's answer.
Updated Oct 13, 2026 7 min read
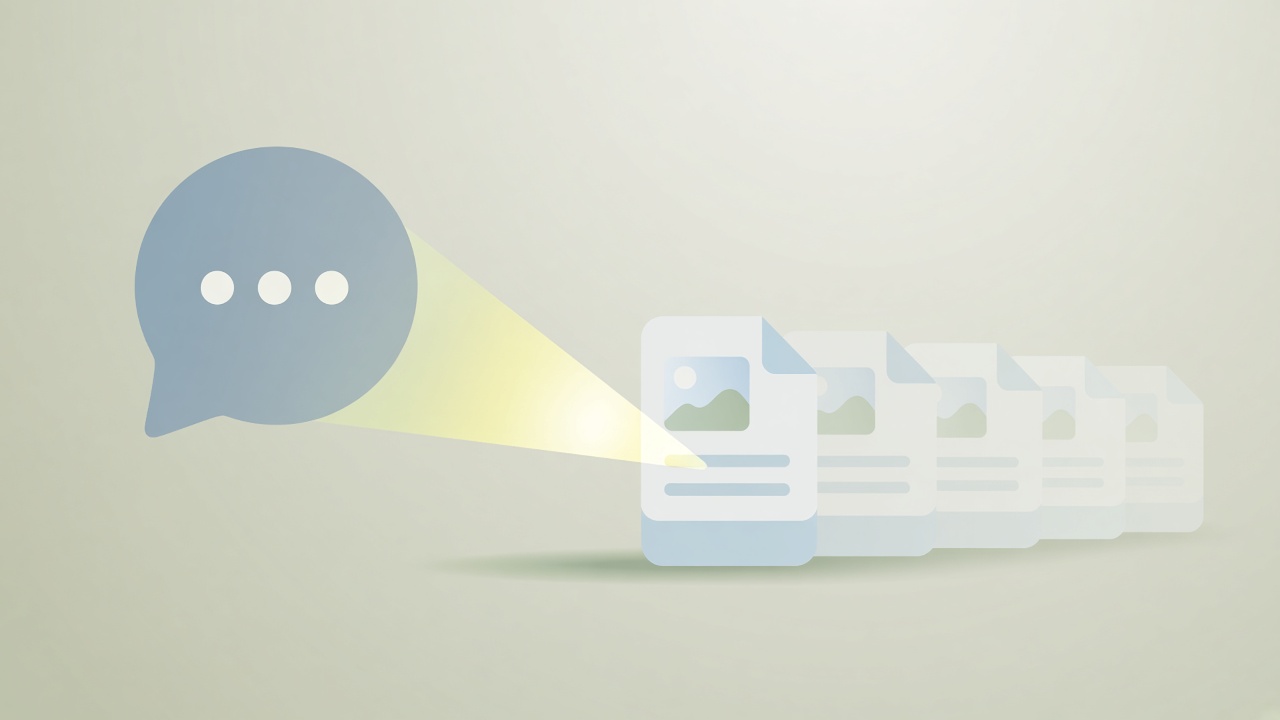
When a chat model "searches the web," it isn't browsing like you do. It converts your question into a search query, gets back a handful of short snippets from a few pages, and writes its answer using those snippets plus whatever it already knew. The citation under the answer tells you where a snippet came from — it does not guarantee the sentence next to it is accurate.
What "the model searched the web" actually means
Search-augmented chat is built on a pattern called retrieval-augmented generation, or RAG. At a high level, when users ask an LLM a question, the AI model sends the query to another model that converts it into a numeric format so machines can read it. That numeric version is matched against indexed web pages, the best-matching snippets are pulled back, and those snippets are inserted into the model's context window alongside your original question. Only then does the model write its answer.
Three things follow from this:
- The model sees fragments, not pages. It gets the paragraph or two around the matching keywords, not the full article, the sidebar, the corrections note, or the comments.
- Retrieval and writing are separate steps. A snippet can be accurate while the model's summary of it drifts, because summarizing is a different operation from finding.
- "Search" is a choice, not a default. Most chat models decide per-message whether a query needs fresh information. A question about a well-known historical fact usually won't trigger a search; a question about this week's prices usually will.
Anthropic made this explicit when it added the feature to Claude: Claude can now search the web, and each response includes inline citations so you can also verify the sources. That "verify" is the operative word — the citation is there so you do the checking, not so you can skip it.
What gets fetched vs. what gets quoted
There's a gap between what the model retrieves and what it shows you. A model might pull five snippets to answer one question but only cite two of them in the visible text — the other three shaped the phrasing without ever appearing as a link. This is why two different chat models can give citation-backed answers to the same question that read quite differently: they didn't retrieve the same pages, and even when they did, they didn't lean on the same sentences.
Interfaces differ in how they surface this. Some put a numbered marker right after the claim it supports; others collect every source into a "Sources" button at the end of the reply that you open separately. Either way, the marker is pointing at where the model found something related, not stamping the sentence as fact-checked.
How to judge a citation in five seconds
Before you trust a cited claim, run it through this checklist:
- Open the link. If you only read the citation number, you've verified nothing.
- Check the sentence actually contains the fact. Search the page (Ctrl+F) for the specific number, date, or name the model claimed. If it's not there, the model inferred or blended it.
- Check who's publishing it. A primary source (the company's own announcement, a government filing, the original study) outranks a blog that summarized the primary source badly.
- Check the date. A citation can be real and still stale — true in March, wrong by June.
- Cross-check numbers across two citations, not one. A single source repeated by everyone isn't two confirmations, it's one fact copied twice.
This matters more than it might seem. One academic study testing several chatbots on citation accuracy found that six out of the eight chatbots tested — all except Grok and DeepSeek — fabricated a substantial portion of the references they produced. That's not a reason to avoid AI search; it's a reason to treat every citation as a lead to check, not a verdict to accept. For a deeper look at why models invent details even with sources in front of them, see Why AI Video Looks Wrong for the visual-model version of the same "confident but unverified" problem, or Reasoning Models Explained for how extra "thinking" steps do or don't reduce it.
Claude vs. GPT vs. Grok: how each one searches
The three major chat families all do retrieval-plus-generation, but they differ in scope and presentation.
| Claude | ChatGPT | Grok | |
|---|---|---|---|
| Triggers search | Per-query, model decides | Per-query, model decides, or forced in Deep Research mode | Per-query; has a separate tool for X |
| Citation style | Inline citations in the response | Inline links plus a "Sources" button at the end | Inline citations, web-grounded like Google Search grounding on Gemini |
| Live social posts | No dedicated social index | No dedicated social index | Yes — a separate x_search tool for posts, profiles, and threads |
| Where it runs | Anthropic's servers | OpenAI's servers | xAI's servers |
On the inline-citation front, Anthropic's own description holds: Claude can now search the web, and each response includes inline citations so you can also verify the sources. Grok's setup is split into two tools — Grok uses xAI web-grounded responses to synthesize answers with inline citations, similar to Gemini's Google Search grounding approach for the open web, and a dedicated tool where the x_search tool lets the agent search X (Twitter) posts, profiles, and threads directly, run server-side by xAI. That second tool is why Grok tends to be the better pick when the question is about something happening on X right now rather than something indexed by a general web crawler.
Do it in Plurel
You don't need to configure anything to get search-backed answers — the capability lives in the chat models themselves.
- Go to plurel.tech. The app opens straight into chat.
- Pick a model that searches. For general web questions, open Claude Sonnet 5.5 (1 credit per message) or Claude Opus 5.5 (1.5 credits) for harder research. For something happening on X right now, open Grok 4.7 (1 credit), which adds X search to web search. For the heaviest multi-source research task, GPT-6 Astra (2 credits) can also read files you attach alongside what it finds online.
- Ask a question that needs current information — a price, a release date, a recent event. Phrase it so a stale answer would be obviously wrong; that's your signal the model needed to search rather than guess.
- Read the citations as they appear, then open at least one before you repeat the claim elsewhere.
- Keep going in the same thread. A follow-up like "check that against a second source" or "what does the official page say" makes the model search again with a narrower target — the chat remembers the conversation, it doesn't start over.
If you want the model to also turn what it finds into a document, it can: the same chat can write a real PDF or spreadsheet from the research it just did, saved to your Document History. For a broader walkthrough of combining search with code and file reading in one thread, see AI Chat With Web Search: Research, Cite, and Run Code. If you specifically want Grok's X-search side explained in more depth, Grok 4.6 vs Grok 4.7: Web and X Search in One Chat covers that. And for prompts that lean on research-heavy output, Claude Opus 5 Prompts: Research, Code and File Tasks has ten you can copy.
Troubleshooting and tips
No citations appeared. The model likely judged your question answerable from its training data and skipped search. Ask directly: "did you search the web for that, or is this from memory?" If you need it to search, say so explicitly — "search the web and confirm the current price."
The citation link is dead or paywalled. Ask the model for a second source on the same claim rather than trusting the first one because it's the only one you have.
Two models give different numbers for the same fact. This usually means they retrieved different pages, not that one is lying. Open both citations and check publication dates — the gap often resolves once you see one is older.
The citation is real but doesn't actually say what's claimed. This is the most common failure. It means the retrieval step found a related page, but the generation step summarized past what the snippet supported. Treat it as "model inferred this" rather than "source confirmed this," and verify separately.
A citation is a pointer, not a proof. Click through, check the date, and you'll get real use out of AI search instead of a confident-sounding guess with a link attached.
Questions people ask
- Does AI chat web search actually read the whole page?
- No. The model gets short snippets around the matching text, not the full article, so it can miss context that sits outside the snippet it was given.
- Why does a citation sometimes not say what the AI claims?
- The retrieval step picks pages by keyword and relevance, not by truth, and the generation step can paraphrase loosely, so the link and the sentence next to it can drift apart.
- Which AI model gives the most reliable citations?
- No model is citation-proof; one academic study found most chatbots tested fabricated a notable share of references, with Grok and DeepSeek performing best in that particular test.
- Can Grok search X (Twitter) posts specifically, not just the web?
- Yes, xAI gives Grok a separate x_search tool for posts, profiles, and threads on X, alongside general web search.
- Is web search free in Plurel's chat?
- Web search runs inside normal chat messages, so it costs whatever that model's per-message credit price is — for example 1 credit on Claude Sonnet 5.5 or Grok 4.7, 1.5 on Claude Opus 5.5, 2 on GPT-6 Astra.
- How do I know if a chat answer actually used web search or just its training data?
- Look for inline citation markers or a sources list under the answer; if none appear, the model likely answered from memory and you should ask it directly whether it searched.
Sources
- Anthropic's Claude Can Search The Web, Closing Gap With ChatGPT
- Anthropic on X: Claude can now search the web
- Does Grok have real-time web search? How it works
- Grok search · OpenClaw docs
- X (Twitter) Search - Hermes Agent - Nous Research
- What Is Retrieval-Augmented Generation, aka RAG — NVIDIA Blog
- Grok and DeepSeek outperform ChatGPT on citation accuracy (arXiv)
Keep going
Reasoning Models Explained: What Thinking Costs You
Reasoning models explained: what extended thinking does before the answer, why it's slower, and when it's worth the extra credits in Plurel.
Updated Oct 4, 2026
ChatGPT vs Claude vs Grok: Which to Use for What
ChatGPT vs Claude vs Grok, compared for writing, coding, research and long documents, with each maker's own claims checked and credit prices shown.
Updated Nov 11, 2026
AI Chat With Web Search: Research, Cite, and Run Code
Learn how AI chat with web search works, why citations matter, and how to research, calculate, and get files done in Plurel.
Updated Oct 5, 2026
Higgsfield Alternative: One Credit Balance for Every Model
Looking for a Higgsfield alternative? See what Higgsfield's presets and pricing actually offer, then compare it with Plurel's one balance for every model.
Updated Nov 10, 2026